Measured, never claimed
Every accuracy figure on this site comes from a public test set we ran ourselves, on the same CPU setup that serves the API. Where we have not measured, we say so.
Kàddu turns spoken Wolof into text and Wolof text into speech, through one small API. It is built in Dakar on open models. Every accuracy number on this page was measured on a public test set, and you can check how.
Kàddu is Wolof for “word”, “speech”, “voice”.
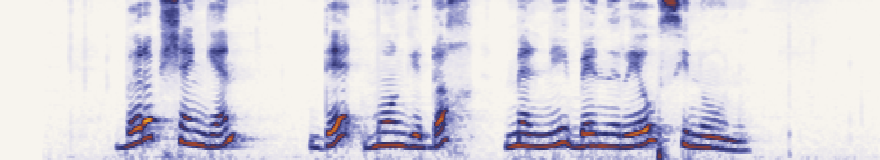
wo_sn · 13069390… · 6.8 s
Human transcript
Bërëb Schengen, de, moo ngi dox melni benn réew ci noonu.
What Kàddu heard
bërëb schengen dé mo ngi dox mélni bénn réew ci noonu
facebook/mms-1b-all · 36% word error rate on this clip
Underlined: differs from the human transcript
Real recording from Google FLEURS (Wolof test split, CC-BY 4.0). Word timings from forced alignment; output from the model we serve.
Every accuracy figure on this site comes from a public test set we ran ourselves, on the same CPU setup that serves the API. Where we have not measured, we say so.
We compare Meta's MMS against fine-tunes from Senegalese and African researchers, then serve whichever wins on the test set, not whichever is biggest.
Wolof has a tiny fraction of the transcribed hours English has. Our roadmap is a consented, openly licensed dataset built with speakers, universities and radio archives.
Wolof is where we start and where we measure. Other languages run on Meta MMS and stay in beta until we benchmark them.
Wolofولوف
Wolof · Wolofal
wol · SN · GM · MR
STT / TTS
Supported
Pulaar
Pulaar (Fula)
ful · SN · GN · ML · MR · NE · NG
STT / TTS
Beta
Mandinkakaŋo
Mandinka
mnk · GM · SN · GW
STT / TTS
Beta
Bamanankanߓߡߊߣߊ߲ߞߊ߲
Bambara · N'Ko
bam · ML
STT / TTS
Beta
Harshen Hausaهَوْسَ
Hausa · Ajami
hau · NG · NE · GH
STT / TTS
Beta
Èdè Yorùbá
Yoruba
yor · NG · BJ
STT / TTS
Beta
Kiswahili
Swahili
swh · KE · TZ · UG · CD
STT / TTS
Beta
Lingála
Lingala
lin · CD · CG
STT / TTS
Beta
Seereer
Serer
srr · SN
STT / TTS
Coming
Sooninkanxanne
Soninke
snk · ML · SN · MR · GM
STT / TTS
Coming
Joola
Jola-Fonyi
dyo · SN · GM · GW
STT / TTS
Coming
Speech-to-text on the Wolof test split of Google FLEURS. Lower is better.
| Model | WER | CER | Speed |
|---|---|---|---|
wav2vec2 MMS · 1B · non-commercial license | 40.0% | 12.2% | 0.93 |
HuBERT base · 95M | 46.9% | 18.1% | 0.17 |
wav2vec2 MMS · 1B · non-commercial license | 47.3% | 15.7% | 0.49 |
w2v-BERT 2.0 · 600M · trained on FLEURS train split (same domain as the test set) | 48.5% | 18.5% | 0.58 |
wav2vec2 XLS-R · 300M · trained on FLEURS train split (same domain as the test set) | 49.2% | 18.7% | 0.15 |
Test set: Google FLEURS wo_sn (test), 239 utterances, 69 min of audio · Hardware: GitHub Actions runner, 2 vCPU x86_64, int8 dynamic quantisation · Measured on 29 Oct 2026
Send audio, get text. Send text, get audio. JSON in, JSON or WAV/MP3 out, no SDK required.
curl -X POST https://api.kaddu.zaleo.dev/v1/transcribe \
  -F "file=@salaam.wav" \
  -F "language=wol"
import requests
with open("salaam.wav", "rb") as f:
r = requests.post(
"https://api.kaddu.zaleo.dev/v1/transcribe",
files={"file": f},
data={"language": "wol"},
)
print(r.json()["text"])const form = new FormData();
form.append("file", audioBlob, "salaam.webm");
form.append("language", "wol");
const res = await fetch("https://api.kaddu.zaleo.dev/v1/transcribe", {
method: "POST",
body: form,
});
const { text } = await res.json();curl -X POST https://api.kaddu.zaleo.dev/v1/speak \
-H "Content-Type: application/json" \
-d '{"text": "Na nga def?", "language": "wol", "format": "mp3"}' \
-o na-nga-def.mp3import requests
r = requests.post(
"https://api.kaddu.zaleo.dev/v1/speak",
json={"text": "Na nga def?", "language": "wol"},
)
open("na-nga-def.wav", "wb").write(r.content)const res = await fetch("https://api.kaddu.zaleo.dev/v1/speak", {
method: "POST",
headers: { "Content-Type": "application/json" },
body: JSON.stringify({ text: "Na nga def?", language: "wol", format: "mp3" }),
});
const audio = new Audio(URL.createObjectURL(await res.blob()));
audio.play();Use the API without a key, within fair limits. Paid plans with API keys and higher limits will come once quality is where we want it.